The Battle for Path

The Battle for Path

Under the surface of the explosion of AI companies and products there is an infrastructure battle taking place – it is a battle to control access to your content and make it a part of an AI company’s training data.  It is a battle to control the path of your information.

There is a spectrum of AI usage types today:

  • Individual users on a chat product using a web browser for chatgpt.com or claude.com or similar.
  • Individual users moving to the desktop client of one of these vendors now packaged as “unified” desktops incorporating chat, coding and work features
  • The enterprise account equivalents of either of the first two, with account controls, budgeting, etc.
  • Token/consolidation products like software development tools which let you pick AI endpoints for coding.  Some of these are configured with your individual API keys to your different accounts and others provide an API token to their service and charge an “uplift” as they route your traffic, basically token re-selling.
  • More comprehensive model routers like OpenRouter (just acquired by Stripe) which let you multiplex and set workflows for where to send different types of queries, and let users pick AI targets dynamically as well.

All of these are trying to ensure that they are in path to your interactions with the LLMs, including potentially your own private LLMs.  Why?  Because they want to capture your users’ interactive sessions with the LLMs.

Hot in the recent news is it appears that mathematicians who spent countless hours independent of LLMs pursuing a significant mathematical challenge, applied their domain and research knowledge to guide and direct their “interrogatory sessions” with an LLM – only to have the LLM company take that synthesized knowledge as their own and claim to have solved the mathematical problem.

The business enterprise stakes are perhaps smaller but omnipresent.

The user might be an expert lawyer, with a deep capable memory, depth of experience in industrial operations litigation, who is using LLMs in their work.  The captured, iterative conversation stream from that person, as they ‘leave’ an LLM session satisfied with the result of the interactions, is likely to be valuable.  The human user directed a synthesis of the knowledge available to the LLM, and the person’s knowledge and lived actions.  This synthesis is likely to have never been captured in the training set.  UNTIL NOW.

The user might be a software designer who through the LLM interactions has that ‘aha’ moment about how to tackle a problem, creating new knowledge.  Even if the LLM tried to “one shot” a response to the designer’s initial prompt, let’s assume the person responded with critique and re-direction.  This interrogative stream likely contains, if not entirely new knowledge to the LLM, then curated knowledge, which adds to the value of the LLM provider.  IF CAPTURED.

Everyone wants you in-path to use your knowledge synthesis as the new training data.  Every day the AI services are being fed “AHA” moments that experts have had while making use of the LLMs as a super knowledge base – but in fact shaping, guiding, let’s say providing, much of the intelligence.

Which leads me to repeat “Kerpan’s Law of AI”:

There are two types of AI companies:

  1. those that tell you the are using your content
  2. those that declare they are not, but are lying


If you do not control your path to LLMs this will be your forever situation.  At Cohesive Networks we think organizations are on a journey from early adoption of LLM’s as a Service (ChatGPT, Claude, Kimi, etc.) and over time will gradually migrate many of these interactions to self-hosted AI (regardless of in-cloud, hosting provider or on-premise).  The key point will be explicit decisions of how much to share with the “as a service” players.

In the past most of us have been too busy, too introverted, too scared, too worried about HR and Legal, to post detailed interactive transcriptions of our thoughts, of team brainstorms, of the fragment of solutions which are not the heart of a product or service, but provide insight and capabilities to products and services.  BUT, in the confessional of the chat interface, given access to something in many ways worse than search, but in other ways better, a more comprehensive knowledge base, we type, guide, shape, drive to new knowledge and give it away.  No, in fact pay for the privilege.

I am not privy to any such fact, but, the LLM as a Service companies have to have a scoring mechanism in place for queries or users, perhaps both.  I would surmise that users whose primary usage is ‘What’s the best cat food for Calicos in February?’ or ‘How do I clean oil stains off my garage floor?’, while perfectly fine customers, might have a low score for bringing “additive knowledge” to the training data.  But there are some users who you might argue should be paid for interacting with the LLMs.

This is why they want your interactions to flow through their path.  Some subset of those interactions are worth their weight in gold as higher quality training material than much of what has been trained on from Reddit, Stack Overflow, etc. Maybe “better” is even the wrong word.  It is at the very least tapping into to the knowledge creation capabilities of a vastly larger number of people.

 WHAT DO YOU DO?

Our belief is that there are the technical components and policy elements to this situation.

In summary, you will need to have corporate policies that define acceptable AI usage.  This will include approved vendors, tools, and modes of usage.  I am not sure what the “carrot” will be, but the “stick” could be something like “violating this policy is grounds for termination, and possibly further ramifications”.  Frankly there will be a number of cases where you will be “catching the cows just out of the barn”, but at least quickly and not long after.  Your policy might allow OpenAI and Anthropic but only via a manged corporate account, maybe browser-based usage only, whilst their desktop applications are not allowed (unless perhaps on an sterile desktop with limited connectivity).  Of course there needs be strictures against feeding PII or PCI data, details of secret projects, corporate actions (possible acquisitions/divestitures).  These details will have to be stated in policy for the protection of your company, the employees (clear expectations, no surprises), and your customers.

You will need technical guardrails and enforcement.  For example, at Cohesive we have had controls like virus scanners and device management.  Moving forward we will be implementing even stricter controls so that many of the AI wrapper applications can be prevented from running on our laptops/desktops.  (My personal view is ‘Only in a container in a VM on a Linux host, in the cloud’).

So far we have proposed policy of “don’t do that or you will get in trouble” and “we won’t let you do that on your work machine”, but what about everything else?  What are the technical components?

At Cohesive we have created an in-path AI Firewall in a virtual appliance that we call WaiF™.

It works in conjunction with our VNS3 Network Platform.  Overall, we think a network virtualization platform is a prerequisite to meet the challenges in a world of LLMs.  While an entire class of vendors have declared the VPN as dead, we are an outlier, put everyone on a VPN, essentially an AI-VPN, at least for accessing LLMs.  Our WaiF solution integrates to your DNS, collaborates with your WAF if you have one, and creates both alert-in-the-wire and block-in-the-wire capabilities while capturing all of the traffic to your approved LLMs, sending the data to object storage, multi-modal databases, data lake infrastructure, etc. that you already have in place.  A simple place to start is getting it all into object storage with a lifecycle retention policy and auditable/browsable by a self-hosted ElasticSearch dashboard.

Aren’t we at Cohesive just trying to get in your path too?  No, we are letting you control your path, we aren’t in control of this infrastructure you are.

This path gateway approach is the beginning of the inference/intelligence/AI journey every organization is embarking on.  Where any given organization ultimately arrives is “to-be-determined”.  There are businesses where using LLMaaS maybe fine, without ever moving to private or local AI.  BUT, even these organizations need an audit trail, need the best practice of having observability, and in large part visible controls over the usage of AI for their business.

For other organizations the AI Firewall with a network platform is the junction point, the place to hook in additional elements, semantic scoring for example.  You can use your organization’s knowledge of itself to score interactive sessions, determining content which just went off to an LLMaaS, but should now be captured separately as knowledge for your private AI.  As the technology evolves you will be able to “front run” specific users and query types to go immediately to local AI as the frontier model capabilities of today become the local AI of tomorrow.  The accomplishment will be keeping more of your specific intellectual property and accumulated intellectual capital in-house.

As the technology is moving so quickly in multiple dimensions, our primary advice is “start”.   You can’t wait for the final “all singing, all dancing” product as it is unlikely the industry is going to be stable anytime soon.  Have joints, junctures, hooks to be in control, and among these, control your path.

Security Compliance: Discipline, Not a Checkbox

Security Compliance: Discipline, Not a Checkbox

Cohesive Networks has completed its 5th consecutive Type 2 SOC 2 examination. Another full operating year of controls examined and confirmed: same auditor, same standard, no exceptions. We publish this every year not because customers ask for a badge, but because we operate in regulated industries where proof of practice matters more than proof of intent.

Examination Details

  • Selected SOC 2 Categories: Security
  • Examination Type: Type 2
  • Review Period: May 1, 2025, to April 30, 2026
  • Service Auditor:  Schellman & Company, LLC

Built Security-First, Before it was Cool

Cohesive Networks spun out of Cohesive Flexible Technologies in 2014 after a clear-eyed assessment: we weren’t a cloud migration company that happened to do security. We were a security and networking company. That distinction shaped how we built everything that followed — internal systems, controls, and architecture all designed to a standard that’s still overbuilt by today’s measure.

VNS3 itself dates to 2008, built originally to secure our own infrastructure, first our Elastic Server Image Factory cluster, then to provide IP address control and isolation in EC2-classic’s open 10/8 network environment. We didn’t build a security product and then figure out how to run it. We ran it ourselves first, on our own production systems, and we still do — internal Overlay Networks for production and support engineering, PeopleVPN for our distributed team.

That history matters.

No Access…

…By design, Cohesive has no access to customers’ VNS3-provided networks. Access and visibility are entirely in the hands of the owner. VNS3 has no backdoor, only Access URLs, API Tokens, and Remote Support multi-party authentication that customers control directly.

For customers using our SecurePass managed service, we extend that same principle rather than suspend it. When our engineers manage a customer’s environment, we do so through a dedicated secure overlay network using the same architecture we build for customers, applied to our own operations. Total network accountability, in both directions.

Looking Ahead

AI is moving into network infrastructure fast, and the compliance frameworks are running to catch up. We’re not waiting. As we build AI-assisted capabilities into the VNS3 platform (look for Connection Advisor with AI Diagnostics beta availability starting in version 7.1.1), we’re engaged with our auditors now on how SOC 2’s existing Trust Services Criteria apply, specifically to AI-assisted operations, not just human-driven ones.

The questions we’re working through are practical ones: What does change management look like when an AI agent is proposing or applying a network configuration change? What evidence do we need to show that AI-assisted access to customer network state is bounded by the same no-backdoor principle as everything else? What does a defensible audit trail look like for CC7 and CC8 when the actor in the log isn’t a person?

We don’t have all the answers yet, and we won’t publish governance claims ahead of the controls that back them up. What we can say is that we’d rather be raising these questions with our auditor while AI features are still being adopted, building governance in from the start rather than retrofitting it after the fact. That’s the same approach we took in 2008, and again in 2014, and again in 2022. It hasn’t changed.

Crab Boil

Crab Boil

Who is boiling whom?

AI Agents making a human stew.

I feel compelled to defensively say, “I use LLMs every day”.

As I see it there are two extremes at the moment: people who don’t use AI and those who are speed-running OpenClaw, Hermes, et. al..

I am in the middle, allowing Claude Code read permissions on specific private source code repos, asking questions leading to assistance, and then creating pull requests based on the interaction. Maybe “left of center” LLM usage if you will.

I do admire the moxie and spirit of adventure as you get to the speed-running end of the spectrum.  But what is the “quid-pro-quo” of agentic AI?  What mix of artificial intelligence versus “artificial life”?

By artificial life I am referring to the seminal “Game of Life” by John Conway and the subsequent generations of a-life research. Wikipedia has a good overview and some visualizations of the a-life entities moving through 2-dimensional space.  This paper from MIT gives a bit more of thought behind these generative experiments.

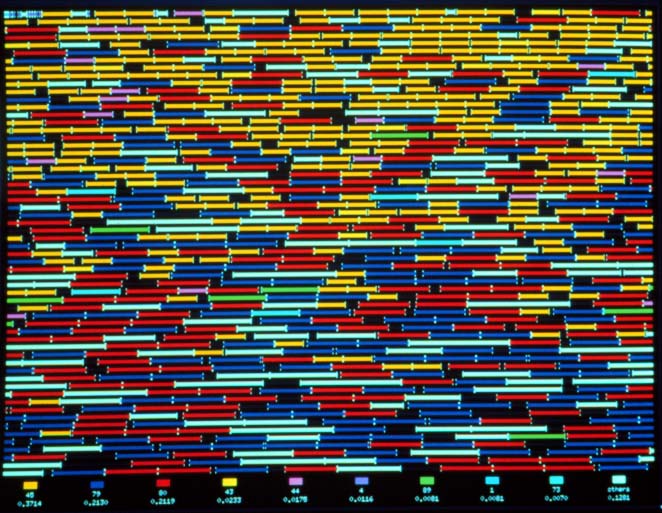
My favorite work in this space was the work done by Thomas Ray quite a number of years ago.

From: Tom Ray, “Tierra Photoessay,”

These experiments show life-like characteristics without much of what would be called intelligence. Simple organisms, in a defined space, and a fairly small number of rules controlling the evolution. At the heart of organism success is the ability to claim space and replicate.

I see this behavior happening in agentic AI. The agents are always driving for more resources, essentially the ability to reproduce. Look at what you get done with 2 agents, what if 10, what if 20? Look what you get done with Claude Pro, how about Claude Max, how about $2k per month in Anthropic API tokens. 2 Mac minis, 5 Mac minis, 10 Mac minis. 10 docker containers, 100, 1000!

The process becomes the product.

Lots of code and apps and blogs and videos come out of these agentic flows, certainly some utility. I myself don’t need calorie or fitness trackers, nor digital servants to make meeting or restaurant reservations, but I see the appeal.

However, I don’t see minimization efforts. No mere ‘satisficing’.

I don’t see the refusals.

The agent saying “Let’s not go down that rabbit hole”.

Maybe I am one of the village elders on the ice floe drifting away, but I resonate with the apocryphal quote from Michelangelo about sculpting “Every block of stone has a statue inside it and it is the task of the sculptor to discover it.”

Part of the ‘uncovering’, part of creation is all the things you don’t do.

Likewise, I believe a good piece of software is the result of all the times you said, ‘NO’.

Now that the cost of “doing” is approaching zero, what is the value of the person or process that has the ability to say “don’t do”?

The problem is “Don’t do” flies in the face of “I want more”.

Agentic AI, OpenClaw and its evolutionary relations entreating our friends, families and employees with “Feed me Seymour!” do present opportunities and costs that we will mature in our understanding of, but do create tangible risks today.

Gee Whiz Kids!

Gee Whiz Kids!

Now that Google has completed the Wiz! acquisition I would love to see Google lead the charge to reduce false positives.

The value of a security scanning product can’t be “look how many things we flagged”. It needs to be “look at all the relevant things we flagged”. There are enough real issues without unnecessary false positives.

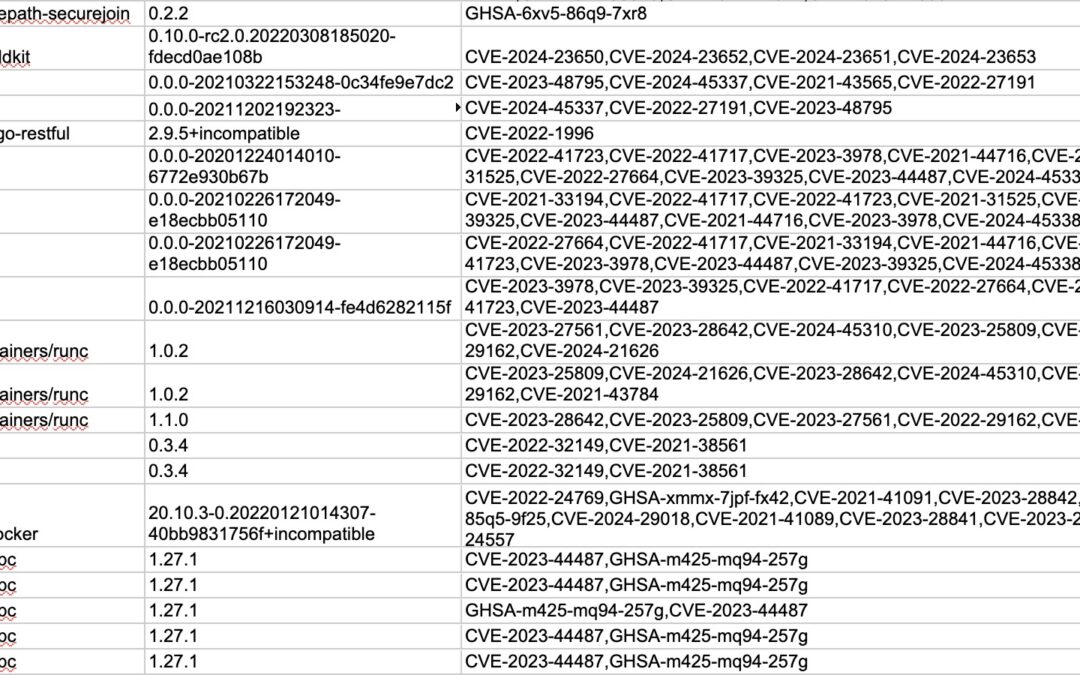
We call these inert alerts “files on disk” alerts.

At Cohesive Networks we regularly get reports of vulnerabilities in “files on disk” which is a source of unnecessary customer consternation and work on both our parts.  (Note: We use typical scanners as well, so I am not saying don’t use them, but some clean up of their approach would be welcomed.)

Here are some of the flavors of “file on disk” alerts we get:

A) Name match.
On your disk you have a file with a “word” in it, regardless of whether it is the actual vulnerable file/code, finding the word in the name of a some other (non-vulnerable) file on disk gets flagged.

B) Guilt by association match.
There is an exploit in library FOO which is often used with library BAR, so BAR gets flagged even in the absence of the other library.

C) No such runtime.
A library you install installs multiple language versions of their functionality, perhaps including a vulnerable Java library, however there is no Java runtime present to execute the vulnerable file.

D) Naive Linux distribution package name compares.
For example, OpenSSL from Ubuntu gets patched against the latest exploits, but the name might still include the word “openssl” with “1.1” The way Ubuntu patches the full .deb file name does tell you if the version is safe or not, but not via a simple word scan. (Yes people should be on OpenSLL 3.x but over the life of 1.x, this was a great example.)

E) A commit to the Linux kernel.
Since the Linux kernel team became its own CVE Numbering Authority the number of CVEs has gone up by about an order of magnitude. This is a philosophical issue more so than a security issue. Most are not practicably exploitable in a finished product containing the kernel. When one of the full operating system distributions points out an issue, that is more likely the time for action.

F) An actual exploit that MIGHT be able to be exploited.
There is an exploit but there is a very specific usage profile for it to be taken advantage of. In this case you do need vendor attestation that the vulnerable usage profile is not in place, but potentially not a candidate for rushed patches or upgrades.

G) An actual, broadly exploitable RCE against an industry common component.
A real emergency like this can be obscured by incidents of type A-E being over-reported. Items in this category obviously need immediate action. Let’s not obscure with a thicket of less relevant items.


When a security team receives these reports with a high number of what I am characterizing as false positives, what are they to do? Many of them want immediate remediation regardless, since how are they to know what to believe? A lot of time and money can be spent on a perceived risk in mere files on disk.

Here is the problem with that interpretation.

If mere “files on disk” are a compromise, then all is lost, everything industry wide is in a state of “compromised”.

All of the package management systems and their “repos” have the vulnerable versions on their disks. These files are not being used. They are “inert”. Just like many of the ones that are showing up in your security scans. In this case they are the files on the disk volumes attached to the servers supporting package installations and patching.

If we are going to claim resources need to be allocated to the above types A-E, then everything is compromised. Their presence on the apt-style repos, yum-style repos, WinGet repos would mean that all of those servers could have been exploited due to the inert file content on their disks. Fun fact, they are not.

I don’t mind getting reports of type “F”. It is incumbent we tell our customer if there is a risk or not, and if so provide patch or upgrade.

I do mind getting a report of numerous vulnerabilities because I have the word “containerd” on my disk and there are CVEs against the golang implementation which is not installed. Or I get flagged for having a python library with the word ‘shlex’ in it because the Rust crate of the same name has a CVE.

What is disappointing is the major scanning products are not new products. They have time in grade, and the expertise to minimize these, but instead are pushing a cognitive load on security teams and their company’s vendors, diminishing resources available for actual risks in an ever more dangerous on-line world.

PS. Regardless of “real” or not, to deal with these false positives efficiently it really helps to use a SBOM system for quick compare of the
flagged item versus what is actually in your product.

Stand Apart – but be Cohesive (part 2)

Stand Apart – but be Cohesive (part 2)

Some more thoughts about standing apart, but being Cohesive.

As Cohesive Networks grows, we do struggle to keep the elements of our company that are fundamental, without being too much of a constraint on evolution and responsiveness to changing markets.

Separate from very specific policies are the stories, mantras, aphorisms that guide you. Not too long ago we had a partner company ask us to tell them why they should work with us. In response we distilled some of the essence we try to hold forth in our words and actions. Here they are with a bit of elaboration.

Our favorite code is code we never write, but we solve a customer problem.
In general people do what you pay them to do, not what you tell them to do. If your reward and identity systems are built around writing and delivering code, you get a lot of code. You get change for change’s sake. We do not do that. The expression of our brutalist approach to software development is:
– Our favorite code is code we never write, but we solve a customer problem.
– Our second favorite code is the code we removed from the most recent release.
– Our third favorite code, is that code, which sadly, exists in order to have a product.

“Run on the cloud not in the cloud.” (Avoid the economically defined architecture)
We go more in depth in this post. To boil it down, the cloud vendors have built massive feature sets that both provide value and extract payments. As a consumer of cloud one needs to ask continuously, am I getting the value?

Unfortunately, certifications in cloud expertises can become so dominant in reward and identity systems that cloud services are incorporated not to serve the ultimate customer, but to serve a certification sense of satisfaction. Customers not acutely aware of this are at risk of implementing an ‘economically defined architecture’, which is a working system architecture, but while correct, it also maximizes cloud vendor revenue. Sometimes “over the top” visible services are a better path to multi-cloud and cost control.

Networks are addresses, routes, and rules; everything else is implementation detail.
This simple statement has gotten me rapidly exited from meetings at one large scale networking vendor interested in acquiring Cohesive Networks. The product management team I was talking to took insult that I could be so reductive. That said, we as a team stand by it. There are names and numbers for things, paths to these things, and the ability to say ‘yes you can’ or ‘no you can’t’ get to those things. The question then becomes how to manifest that in a way that gives enough power to someone with in-depth network expertise, but also empowers a person “just trying to connect these two things”.


Do your best to not surface implementation detail in customer experience.

This is the corollary to above. We definitely have not succeeded at this in all parts of the VNS3 Network Platform, but we try.  Obviously we provide a networking system, so there are elements of the implementation that have to surface technical detail.

For example, there are such things as “IPsec connections” and IPsec has elaborate configuration constraints which need to be managed. That said, it can probably still be simplified. As an example, our single page UI for defining an ipsec endpoint tries to achieve this objective. I had one user tell me, “The first time I saw your IPsec UI, I wondered what college intern wrote it. After I used it for a while I decided it was genius.”

Support is the critical sales function.
Some companies will claim this to be true, and then they have the support staff hound you with upsell offers, surveys, and other actions that have NOTHING to do with solving your problems. What we mean at Cohesive is, when a customer has a question or concern, your ability to quickly and knowledgeably assist them is a critical part of your trust relationship.

There can be no ulterior motive other than you want to help them in that distinct moment. In our case where the majority of our customers are SaaS/BPaaS providers, initial connectivity issues are a key obstacle to time-to-value for both the SaaS provider and their customer. Eliminating any issues in this dimension helps our customer and their customer alike.

FNA – full network accountability is a company culture.
Multi-party networking and security by definition is a collaborative endeavor. When there is a problem, there is a risk that collaboration devolves to finger pointing. When you have a solution like the VNS3 Network Platform that is SO reliable it can be difficult to look at your self as the culprit when a customer has issues. Well over 90% of all inbound “P1” support issues that we receive come as a result of our customer’s customer has <changed misconfigured broken> something in the network path.

It is tempting to enter the interaction with a bias towards a “it’s not us, it’s you” mindset. To counter this we practice what we call “Full Network Accountability” which means to the best of our ability we will work with our customer, their customer, their customer’s outsourced networking people, whomever, to solve the problem. In doing so, our team has to start with the premise, that no matter how unlikely, our customer has run into a never-before experienced, one time only, horrible bug in Cohesive VNS3, until proven otherwise. Then we move forward through the entire connection path with customers (as desired) to find the ultimate issue.

This list is not exhaustive, but is indicative of how we have approached the long term health of the VNS3 platform and our company Cohesive Networks. Software, security and network skills are the table stakes for serving customers in our space, but how to have those skills and deliver them to customers through time and across hype cycles is the additional critical capability that we strive for.

3 Key Steps to GDPR Compliance

3 Key Steps to GDPR Compliance

Don’t be caught off guard by GDPR requirements in 2018!

A recent study by KPMG of the boards of FTSE 350, few are prepared for the General Data Protection Regulation, or GDPR. All new data your organisation gathers should include more clear evidence of data collection consent and opt-out options. How should IT teams prepare for the upcoming changes? Which initiatives should be a part of your program to be compliant?

Penalties for not complying with GDPR will be steep. Organizations in breach of GDPR can be fined up to 4% of annual global turnover or €20 Million (whichever is greater). While this is the maximum amount an organisation will face, the requirements are rigid for all levels of infringements. GDPR has a tiered approach to fines so organisations might be liable for multiple offenses. Internal IT teams and legal depatrments should take note – the GDPR applies to any company that controls data or processes data — ‘clouds’ are not exempt.

Which initiatives should be a part of your program to be compliant with GDPR?
The first, major step to complying with GDPR is to understand the data the organisation holds. Multiple departments will likely hold lists of personal information, such as email lists for marketing, human resources’ personnel files, and so on. Understanding what you must protect is the first step to protecting it.

Takeaway: Any organisation that collects or processes data of an EU citizen should comply with GDPR.

At the core, the GDPR requires data protection by design. Organisations must design data security into business processes.

Another requirement is “pseudonymisation” or the process of transforming personal data in such a way that the end data cannot identify the specific data. An example is encryption. Additionally, the GDPR also requires the associated information, like the decryption keys, must be kept separately from identifying data.

Specifically, IT teams can ease into GDPR with better monitoring and management. Automating any part of network scanning, log analysis, and compliance tracking can speed up time to compliance.

Next, teams should re-evaluate access controls to sensitive data. With cloud-based systems, it should be easier to implement strong authentication programs to apply the rule of “least privilege” required for each application.

Finally, add encryption in-transit to any existing security best practices. Cloud providers offer excellent encryption for data at rest, but only some services and intra-region transfers have data-in-motion encryption. Any data traveling between cloud regions, traveling over the public internet, and between organisation locations should be encrypted.

How can Cohesive Networks help you?

VNS3 helps meet data security measures for data privacy compliance:

  • Encrypt data in transit using VNS3’s IPsec tunnels to connect to all data sources and applications
  • Protect Personal Data by encrypting all data across open public networks
  • Guard against Vulnerability with a VNS3 intrusion detection system (IDS)
  • Maintain Strong Access Control by controlling access to data and encryption keys
  • Enhance Data Portability with a VNS3 overlay network over the top of any cloud or virtual network